Machine learning · Independent project
XGBoost Tennis Model
A tennis win-probability model — and the instrumentation built to prove, honestly, whether it beats the market it bets against.
Project Summary
End-to-end ML tooling for tennis prediction: a calibrated XGBoost model estimates each player's win probability from years of scraped match data, and a trading layer bets it against real prediction-market prices when the two disagree. The interesting part is not the model — it is the evaluation that keeps it honest on live, settled money.
- Status
- Independent
- Role
- ML engineer + backend + UI
- Stack
- Python, pandas, XGBoost, Flask, R (ggplot2)
- Code
- Private repo
1. Overview
I built a live tennis prediction-and-trading system. An XGBoost model estimates each player's win probability from years of scraped match data, and a trading layer compares that probability against real prediction-market prices (Polymarket US, Kalshi) to place a bet when the model and the market disagree enough to be worth it.
The hard question for a system like this isn't “is the model accurate?” A liquid market is already a very strong forecaster, so matching it just means paying fees to agree with the price. The real question is whether the model is right in a way the market is wrong, and whether that difference actually makes money after costs. This project started from that practical framing: can a disciplined feature pipeline produce probabilities that are not just plausible, but tradeable — and can I prove it on real, settled bets rather than a flattering backtest?
2. What I Built
The pipeline cleans per-player match histories, normalizes naming and tournament context, builds surface-aware and form-sensitive features, and feeds them into an XGBoost classifier with calibration. A market-adjustment step then blends the raw model toward the live price to correct for the “winner's curse” — a raw model that disagrees hard with a sharp market is usually overconfident. On top of that sits a Flask interface for inspecting predictions and a trading layer that logs every bet to a settled ledger, which is what the evaluation below is built from.
3. Does It Actually Work?
A prediction model that places bets is easy to fool yourself about. So I hold the system to three questions, in order — and each of the figures below answers exactly one of them:
- Is the probability any good? Is it calibrated against what actually happened?
- Is it better than the price it bets against? The market is a strong, liquid, competing forecaster.
- Does being “more right” pay? Does the gap between model and price convert into money after fees, spread, and slippage?
Every number here comes from real, settled trades placed against live prices — roughly seventeen resolved bets with real (small) money, not a backtest. Read left to right, the charts go from “is the forecast any good” to “did it pay.”
3.1 · Forecast error — is the probability good, and better than the price?
A Brier score is the mean squared error of a probability forecast against what actually happened: 0 is perfect, lower is better. The dashed line is the base-rate reference — the score you'd get by ignoring every match and always forecasting the observed win rate. A bar has to sit below that line to be adding any skill at all.
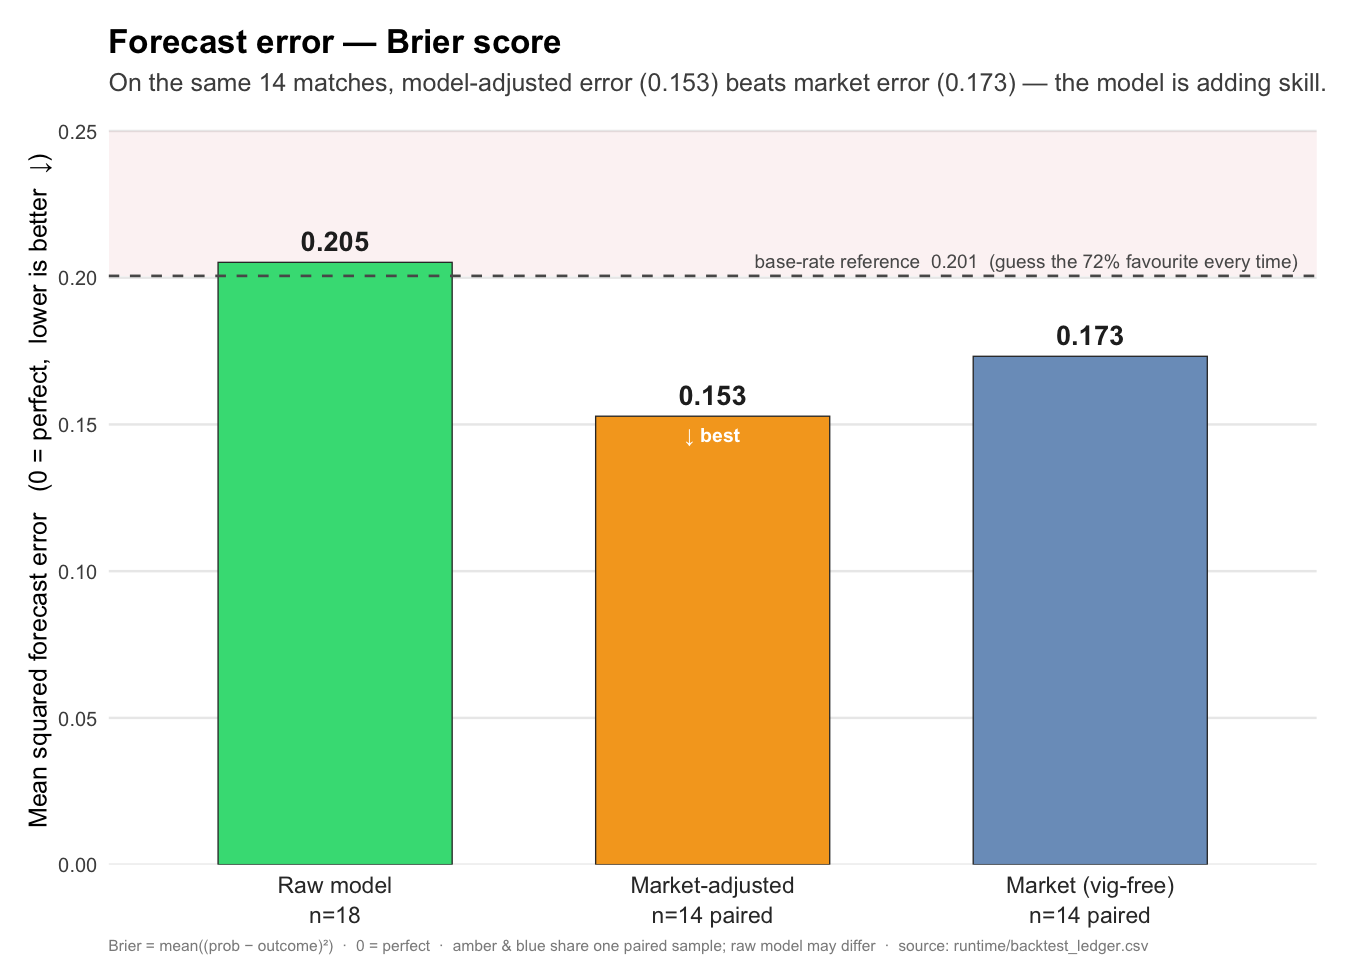
On the shared 14-match sample, the market-adjusted forecast (0.153) beats the market's own vig-free price (0.173) — the model is adding information the price does not have. Two things are worth stating plainly, because they make the result more credible, not less. First, the raw model (0.205) is actually a hair worse than the base rate (0.201): on its own it is roughly no better than guessing the favourite. Second, the market adjustment is what creates the skill — it pulls 0.205 down to 0.153, and that is the bar that clears the price. The value isn't the raw model; it's knowing how much to trust it against a sharp market. That is the genuinely non-obvious engineering insight in the whole project.
3.2 · Forecast vs market vs result — when it disagreed, who was right?
Each column is one settled match. Two dots — the model's win probability (amber) and the market's implied probability (blue) — are connected by a line, and the actual outcome sits at the extremes: 100% if that pick won, 0% if it lost. Whichever dot lands closer to the outcome was the more accurate forecaster, so the chart does the comparison for you: the closer forecast is drawn as a bold, ringed dot and the one that missed fades out, with each column tinted green (won) or red (lost). Columns are ordered so the model's most aggressive disagreements with the price sit on the left.
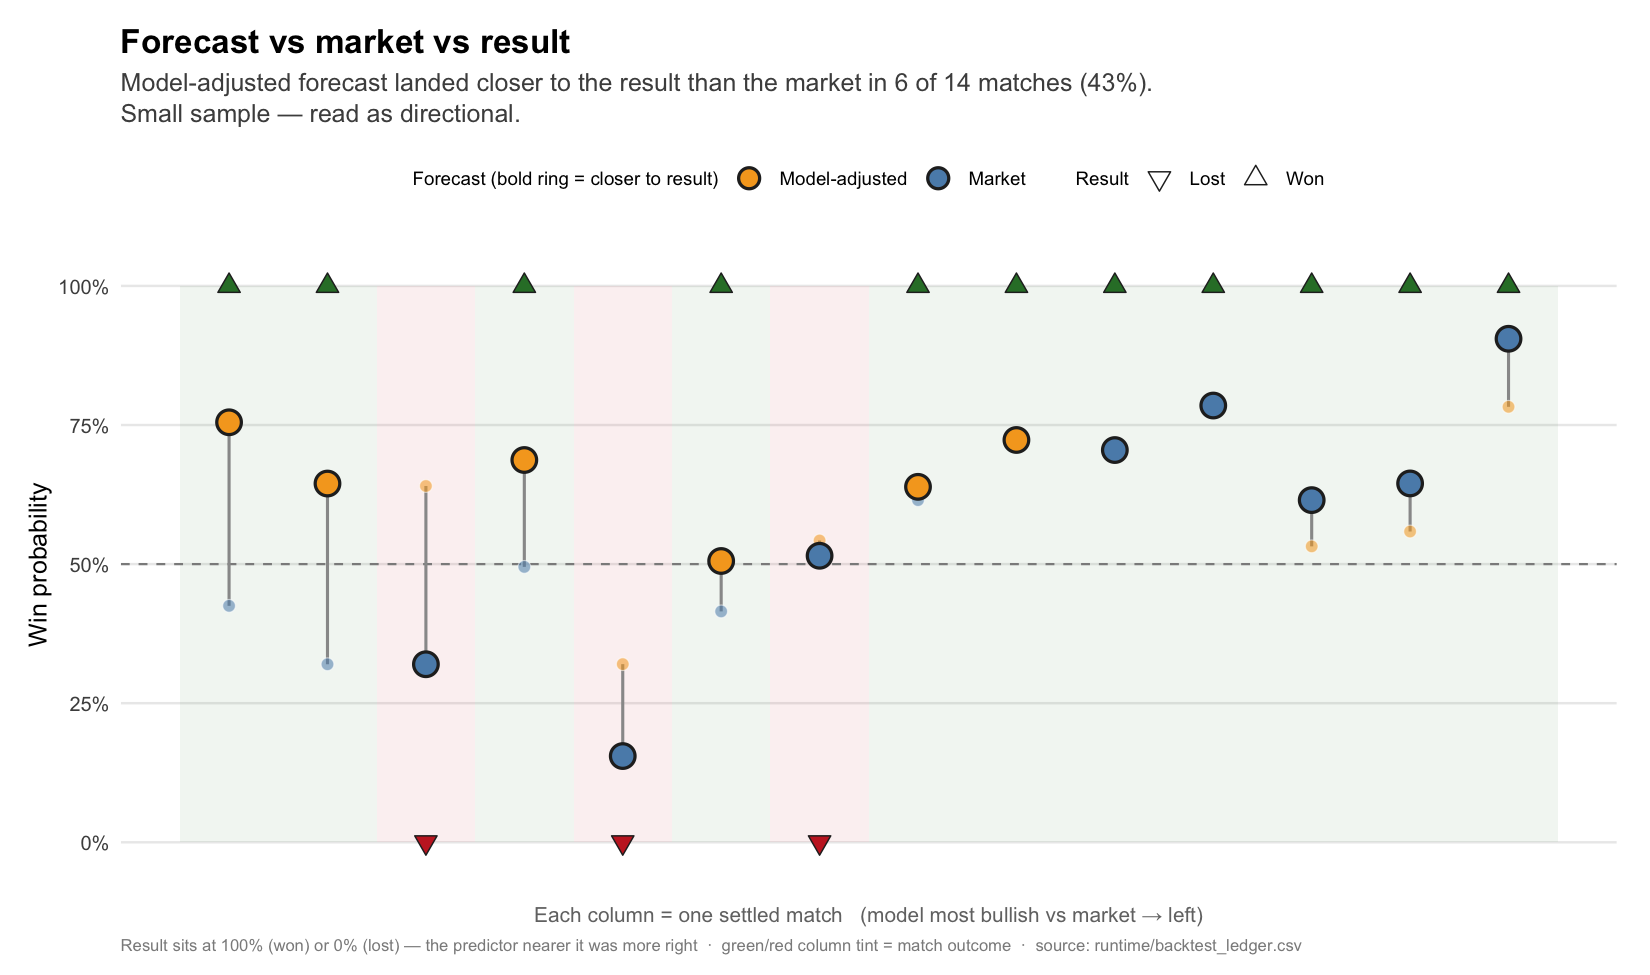
The model-adjusted forecast landed closer to the result than the market in 6 of 14 matches (43%) — read that as a tie on a small sample. The pattern on the left side is the honest takeaway: exactly where the model disagreed most aggressively with the price (the red, lost columns), the market's more cautious number was usually the closer one. The model's boldest disagreements were a coin flip between insight and overconfidence — which is precisely why the market adjustment in 3.1 exists, and precisely why it earns its keep.
3.3 · Did claimed edge convert to money?
This is the one that matters most. Every dot is one real, settled trade. The x-axis is the claimed edge — how far the model's probability sat above the market price, in percentage points; right means the model thought the pick was underpriced, which is the reason the bet was placed. The y-axis is realized return on cost — the actual money that trade made or lost as a percent of what I paid to enter, after fees and slippage. Color is won (green) / lost (red); dot size is stake. The one quadrant that counts is top-right — “model right & paid” — because a big disagreement only matters if the mispricing is large enough to overcome trading costs and model error. The blue line, with its confidence band, is a fitted answer to the core question: does more claimed edge translate into more realized return?
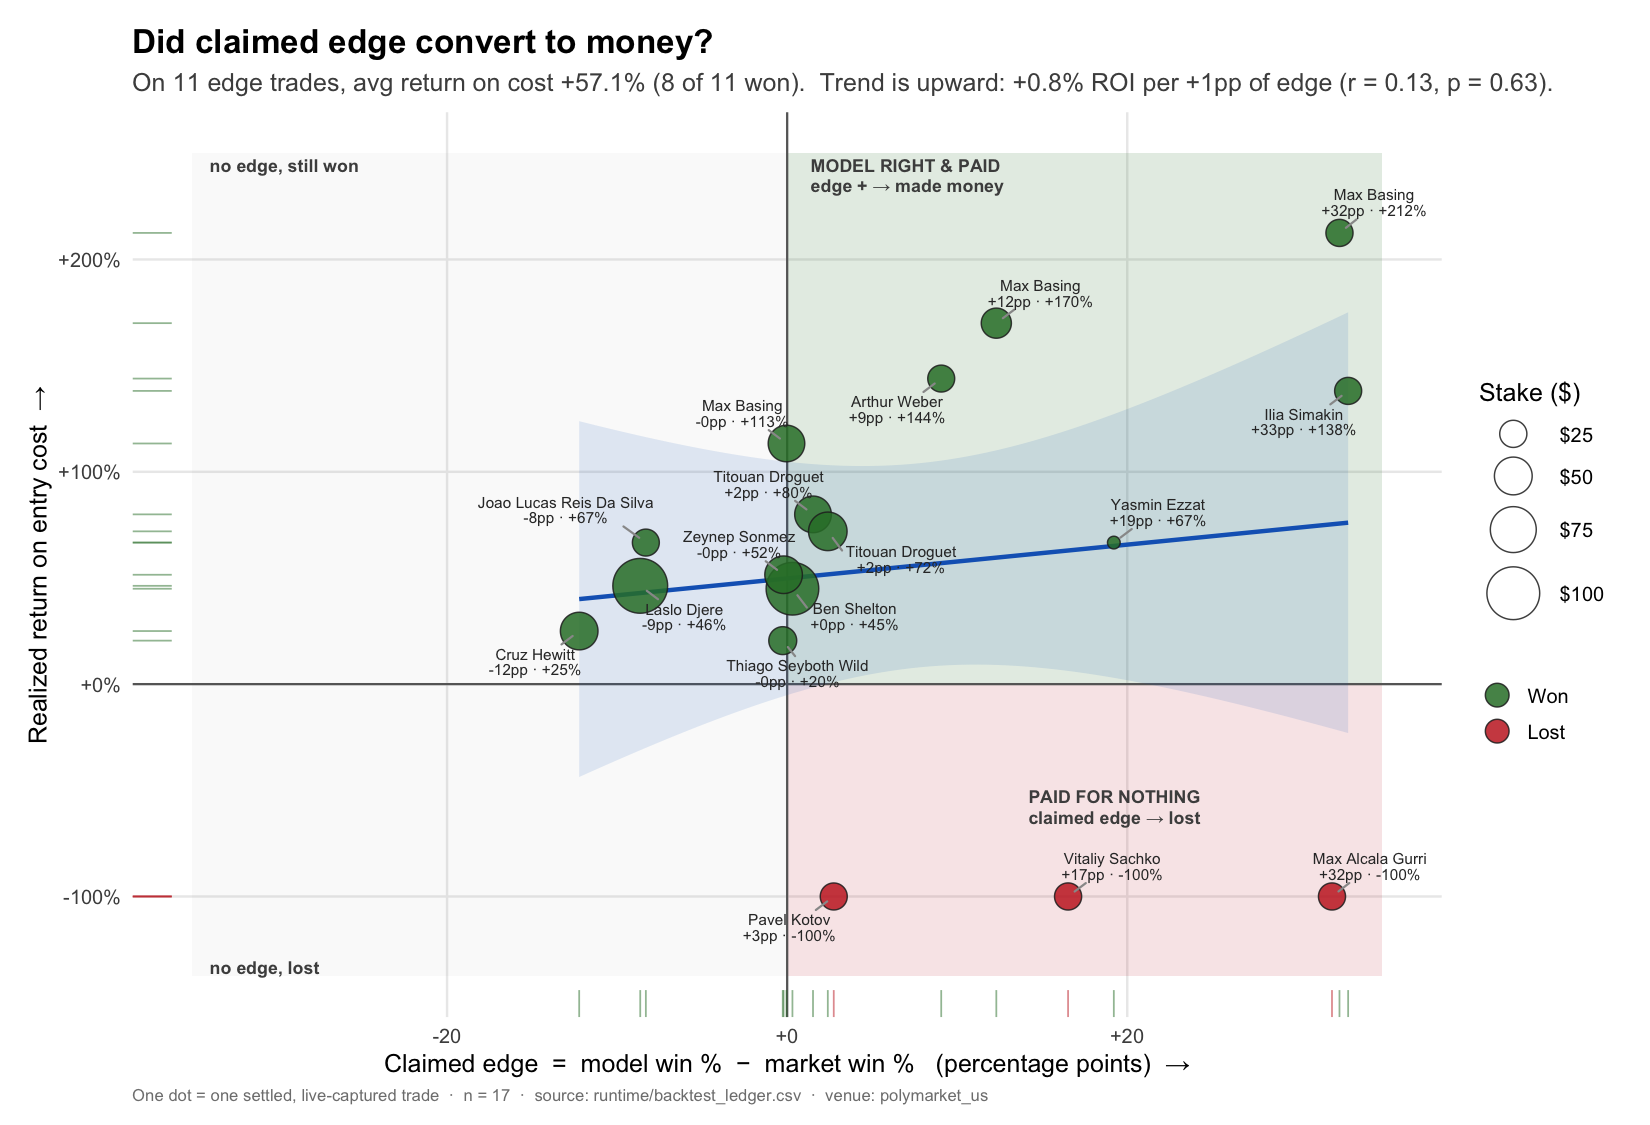
On the 11 trades where the model claimed an edge, average return on cost was +57% (8 of 11 won) — so on this sample, the mispricings the model flagged were real enough to clear costs. But the trend line is only weakly positive and not statistically significant: +0.8% return per extra point of edge, correlation r = 0.13, p = 0.63. The three red dots sitting at −100% in the bottom-right are the reason — real claimed edges, bet with confidence, that went to a total loss.
So the truthful conclusion is the careful one: positive-edge trades were profitable on average, but “bigger edge → bigger profit” isn't yet proven — the sample is 17 trades and the variance is large. Stating that limitation out loud is exactly what separates understanding a metric from just plotting it.
3.4 · What the numbers say so far
Put together, the three charts are one argument in three steps. A model that trades has to beat the price, not just be accurate — and the market-adjusted model does (0.153 vs 0.173), with the twist that the raw model doesn't, so the adjustment is the real innovation. When it disagrees, it's roughly a coin flip on this sample, and its boldest disagreements are the riskiest. And it makes money on average where it claims an edge (+57%), though “more edge → more profit” is not yet a proven relationship.
The through-line is the part worth putting my name on: I didn't just build a model, I built the instrumentation to know whether it actually works — and I'm honest about what seventeen live, settled trades can and cannot tell me. Promising early results with real money and stated sample-size limits are, to a technical reader, more convincing than any cherry-picked win rate.
4. System Architecture
Data ingestion
Historical match records are collected and standardized into per-player histories with consistent naming and tournament metadata.
Feature engineering
Surface splits, recent form, opponent context, and fallback profile logic are assembled into a structured feature vector.
Modeling & adjustment
An XGBoost classifier is trained with time-aware evaluation, calibrated, then blended toward the live market price.
Trade & ledger
Edge-gated bets are placed against live prices and logged to a settled ledger — the raw material for every chart above.
5. Technical Challenges
The hardest part was not training a classifier. It was keeping the entire workflow honest. Tennis data is noisy: players appear under inconsistent names, surface context matters, recent form matters, and evaluation can become misleading if future information leaks into training features. And once real bets are involved, a second kind of honesty matters — reporting the losing trades and the insignificant trend line as loudly as the +57% average, so the evaluation measures the system rather than flattering it.
6. What This Project Demonstrates
More than a single model, this project shows how I approach end-to-end engineering work: define the problem, clean and shape the data, design features around the domain, validate carefully, and — just as importantly — build the measurement that tells me whether the result is real. That combination of ML, backend logic, and honest evaluation is what makes this a strong representation of how I like to build systems.